Scientific Products
Machine Learning (ML) Explorer
Registered users with activated accounts can access ML Explorer using the button below.
New to ML Explorer? Learn how to create an account on our Registration Information page, or sign up directly through the Registration Portal.
ML Explorer
Modern Online Tools for Machine Learning and Scientific Data Analysis
ML Explorer is a comprehensive, browser-based machine learning platform developed by Atomistica. As part of the Atomistica Explorer Suite, it provides an accessible collection of tools for data preprocessing, predictive modeling, model evaluation, and interpretation of machine learning results. Designed for researchers, students, educators, and professionals, ML Explorer supports data-driven investigations in chemistry, physics, materials science, engineering, and related scientific disciplines. The platform combines established machine learning algorithms with advanced analytical capabilities, enabling users to prepare datasets, train predictive models, evaluate their performance, and generate predictions for new data.
ML Explorer enables comprehensive machine learning workflows without requiring programming experience or specialized software installation. Its intuitive graphical interface makes machine learning accessible to users with different levels of computational expertise.
ML Explorer is freely available for academic research and educational purposes. Commercial use is subject to separate licensing terms and conditions. Organizations and individuals interested in commercial applications are encouraged to contact Atomistica for further information.
Citation of relevant scientific publications is mandatory when using ML Explorer in research leading to scientific publications. Users are required to acknowledge the software and cite the appropriate references, as described on our dedicated How to Cite page.
Data Preparation and Preprocessing
Prepare and organize scientific datasets for machine learning using integrated data processing tools:
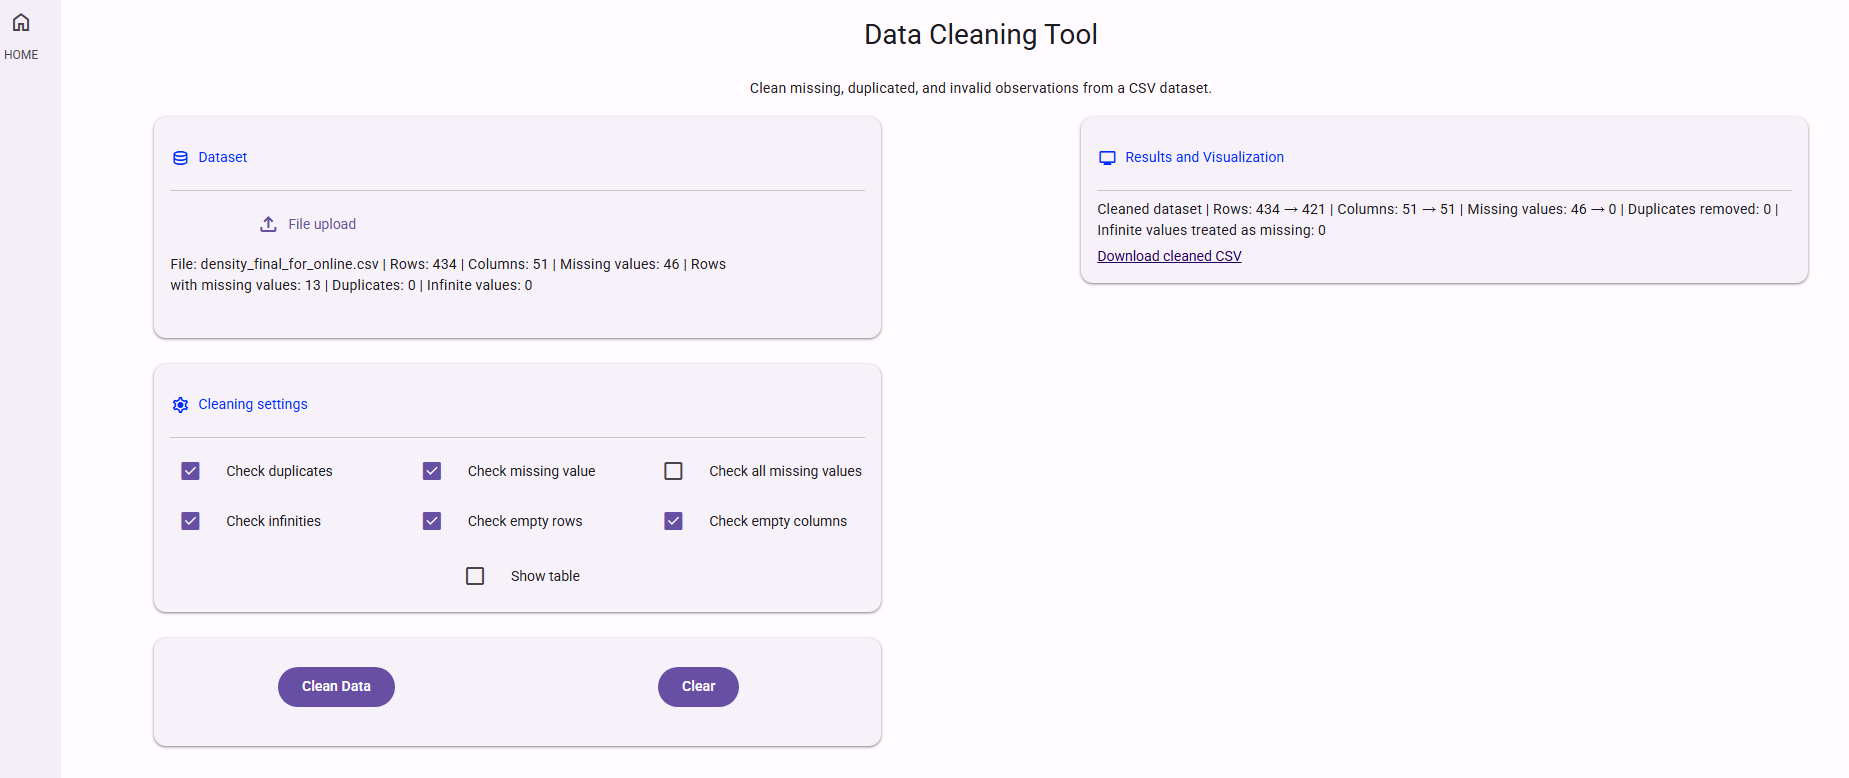
- Dataset Cleaning – Identify and remove duplicate records, missing values, infinite values, and invalid data entries.
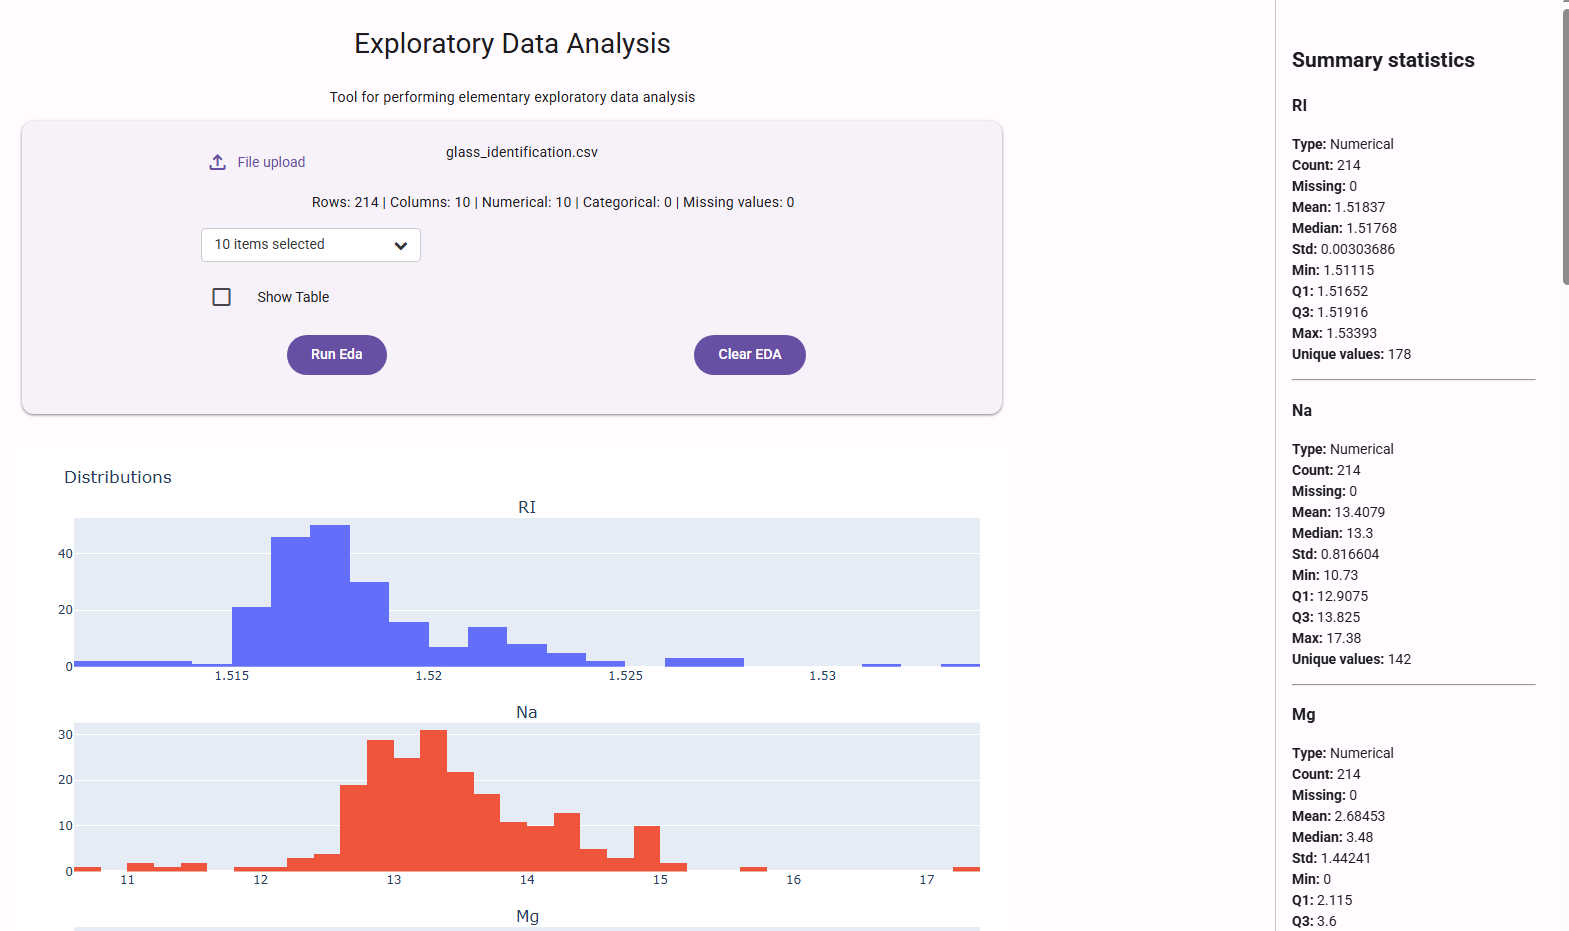
- Exploratory Data Analysis (EDA) – Examine dataset characteristics, descriptive statistics, variable distributions, and relationships between numerical features.
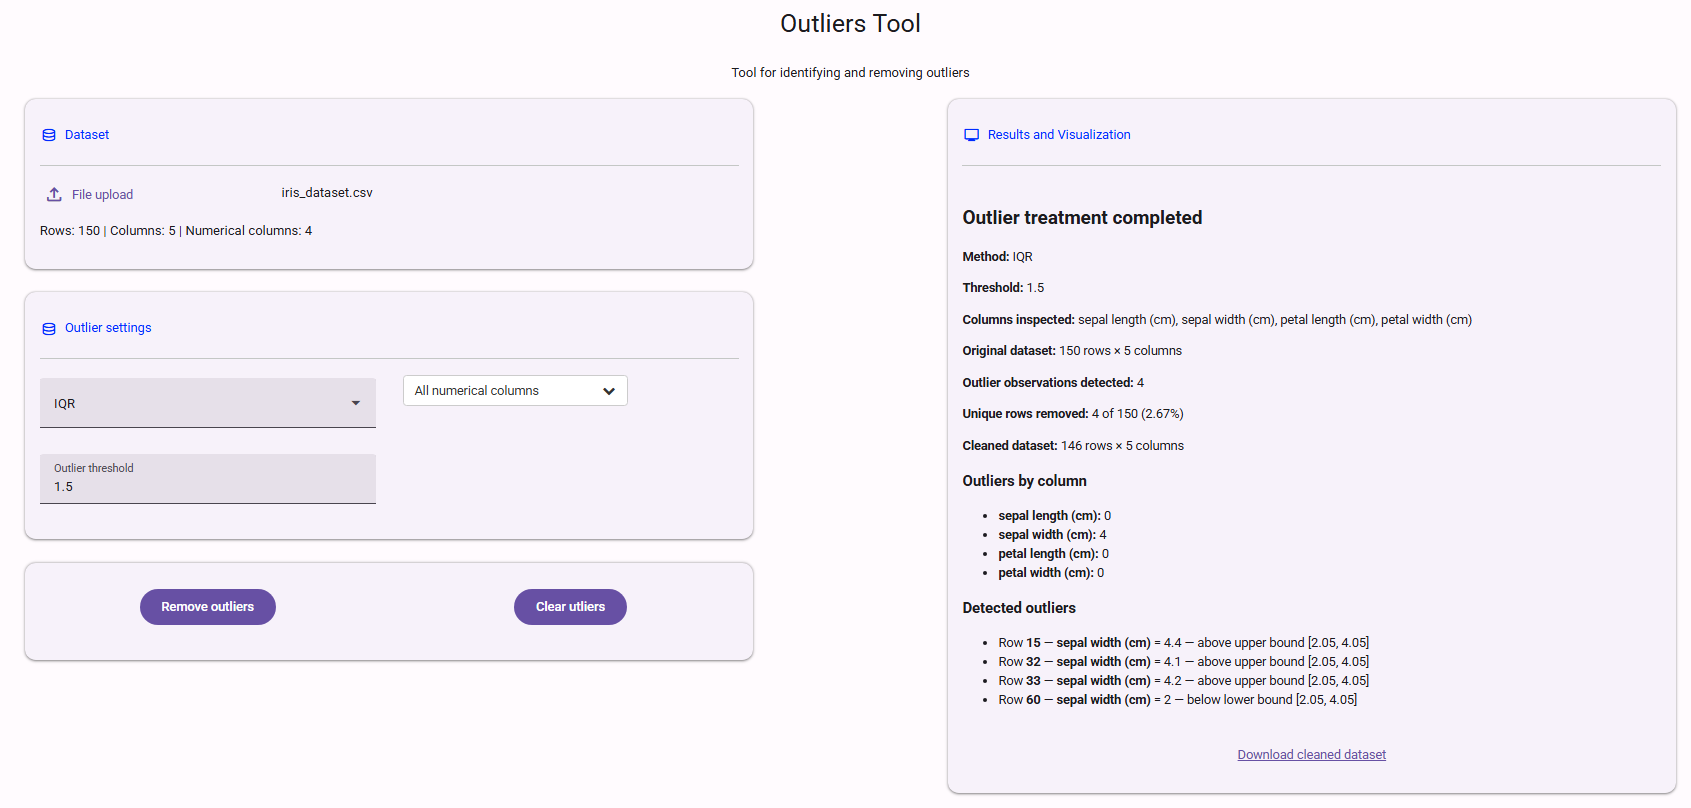
- Outlier Detection – Identify potential outliers using Z-score and interquartile range (IQR) methods.
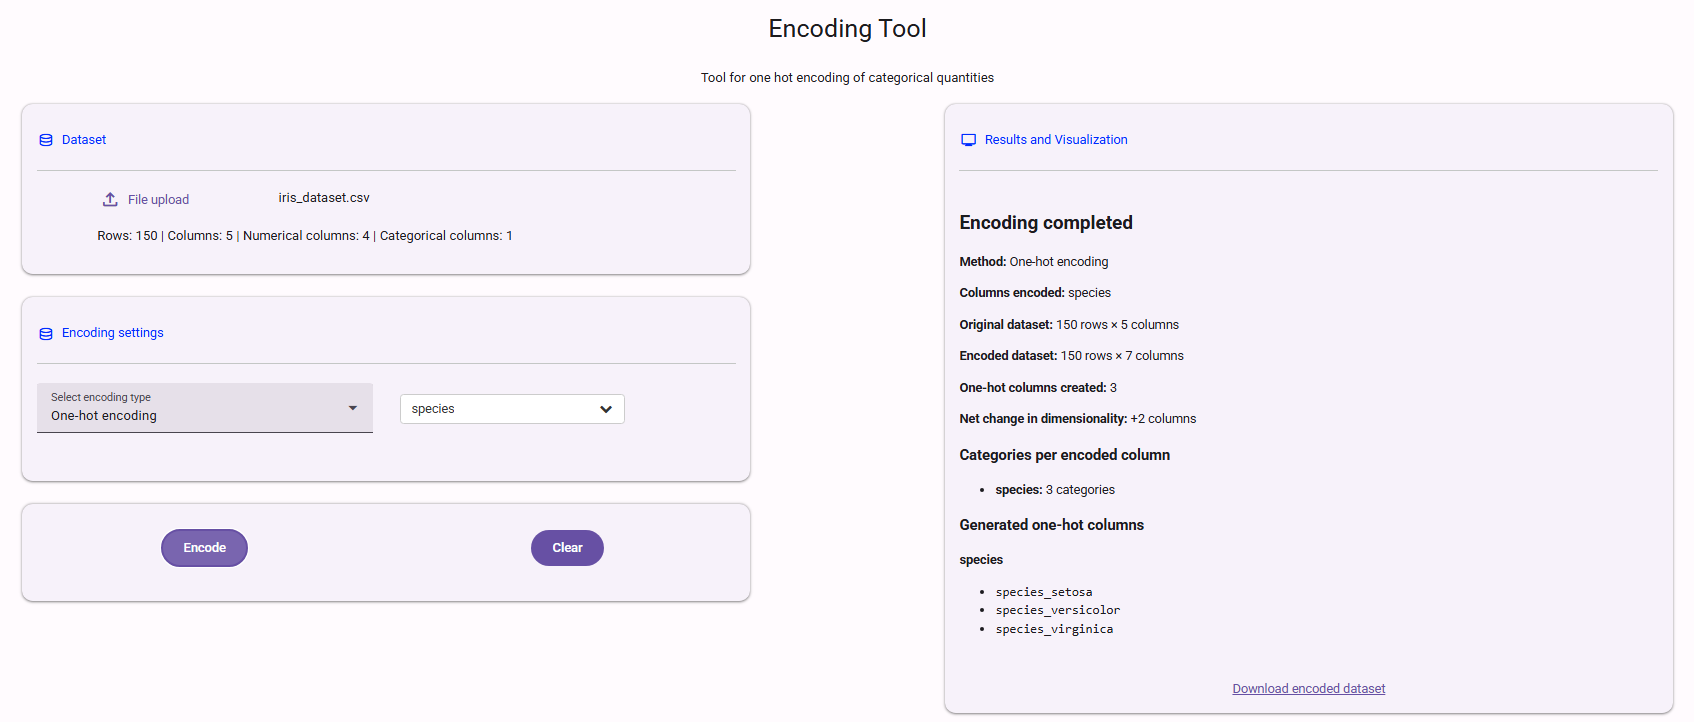
- Categorical Encoding – Convert categorical variables into numerical representations using label encoding and one-hot encoding.
- Data Transformation – Apply logarithmic, square-root, Box–Cox, and Yeo–Johnson transformations to numerical variables.
- CSV Utilities – Convert, format, and standardize datasets for further analysis and modeling.
These tools simplify the preparation of experimental and computational datasets, helping users identify data quality issues before model development.
Exploratory Data Analysis and Dimensionality Reduction
Investigate dataset characteristics and explore relationships between variables before developing predictive models:
- Descriptive Statistics – Examine fundamental statistical properties of numerical variables.
- Distribution Analysis – Visualize variable distributions using histograms, box plots, and violin plots.
- Scatter Matrix Visualization – Explore relationships between multiple numerical variables.
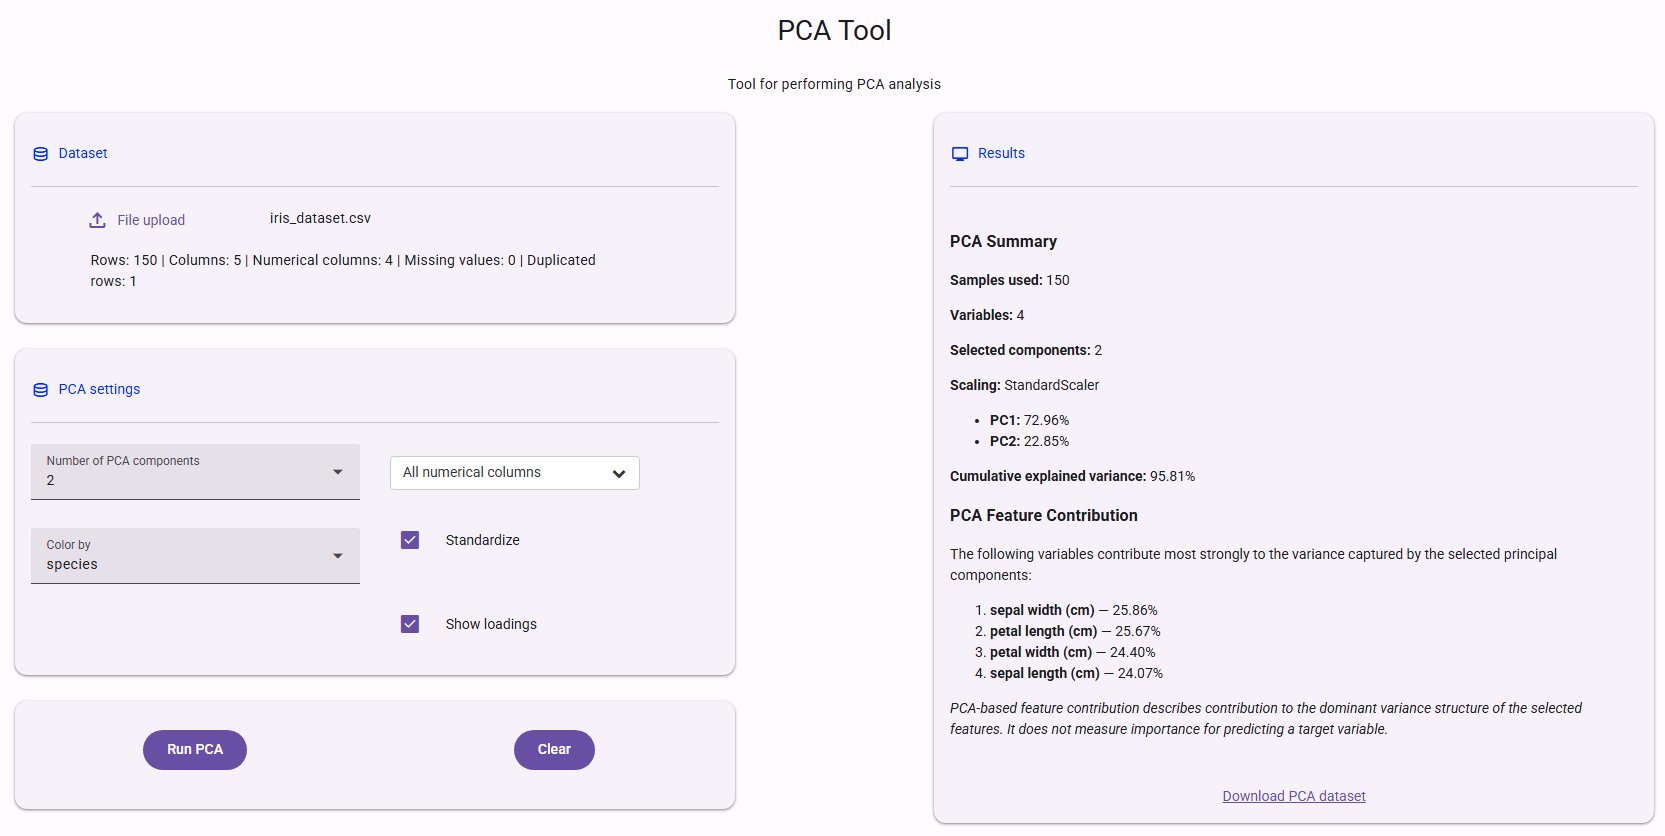
- Principal Component Analysis (PCA) – Reduce dataset dimensionality and identify dominant patterns of variation.
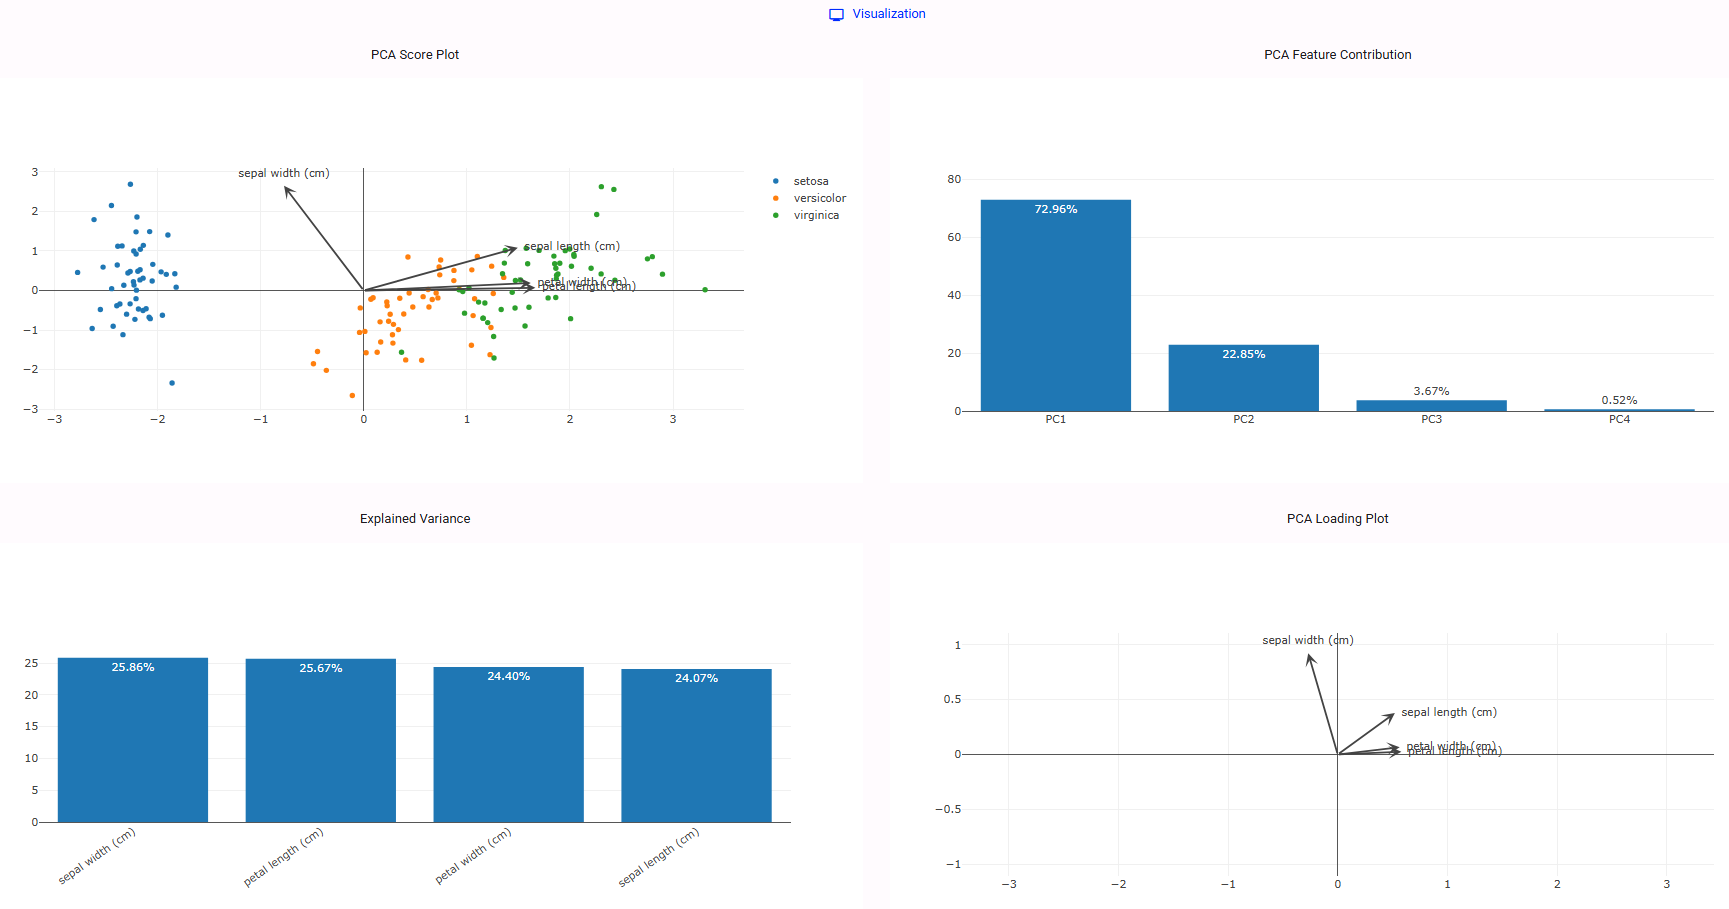
- Explained Variance Analysis – Examine the proportion of variance captured by individual principal components.
- PCA Visualization – Generate two-dimensional and three-dimensional representations of observations in principal component space.
PCA Loadings and Biplots – Investigate the contributions of original variables to principal components.
These capabilities support exploratory investigations, feature analysis, and the identification of patterns in multidimensional scientific datasets.
Machine Learning for Regression
Develop predictive models for continuous numerical properties using established machine learning algorithms:
- Linear Regression – Model linear relationships between input features and target variables.
- Ridge Regression – Apply L2 regularization to improve model stability and reduce overfitting.
- Lasso Regression – Apply L1 regularization for coefficient shrinkage and feature selection.
- Decision Tree Regression – Model nonlinear relationships using decision-based learning.
- Random Forest Regression – Combine multiple decision trees for ensemble-based predictions.
- Support Vector Regression (SVR) – Model complex relationships using support vector methods and kernel functions.
The regression module supports customizable model parameters, optional feature scaling, training and testing datasets, and performance evaluation using R², MAE, MSE, and RMSE.
Integrated graphical tools enable users to examine predicted versus observed values, analyze residuals, and assess model performance.
Machine Learning for Classification
Build predictive models for categorical outcomes using widely applied classification algorithms:
- Logistic Regression – Perform classification using probabilistic linear models.
- k-Nearest Neighbors (kNN) – Classify observations based on the characteristics of neighboring samples.
- Support Vector Classification (SVC) – Separate classes using support vector methods and kernel functions.
- Decision Tree Classification – Develop interpretable classification models using decision-based learning.
- Random Forest Classification – Combine multiple decision trees for ensemble-based classification.
Users can configure model parameters, select input features and target variables, and evaluate classification performance using training and testing datasets.
The classification module provides confusion matrices, classification reports, and additional tools for understanding model predictions and classification performance.
Model Validation and Performance Evaluation
Assess predictive performance and model generalization using integrated evaluation tools:
- Train/Test Splitting – Divide datasets into training and testing subsets for independent model evaluation.
- Cross-Validation – Evaluate regression and classification models using K-Fold, Stratified K-Fold, and repeated cross-validation approaches, as applicable.
- Regression Metrics – Calculate R², mean absolute error (MAE), mean squared error (MSE), and root mean squared error (RMSE).
- Classification Metrics – Examine precision, recall, F1-score, and confusion matrices.
- Graphical Evaluation – Explore model performance using predicted-versus-observed plots, residual plots, and other diagnostic visualizations.
- Optional Feature Scaling – Apply standardized feature scaling within supported machine learning workflows.
These capabilities help users evaluate model reliability, compare predictive approaches, and identify potential overfitting.
Model Interpretation and Feature Importance
Understand how machine learning models generate predictions using integrated interpretability tools:
- Permutation Feature Importance – Evaluate the contribution of individual input variables by measuring changes in model performance.
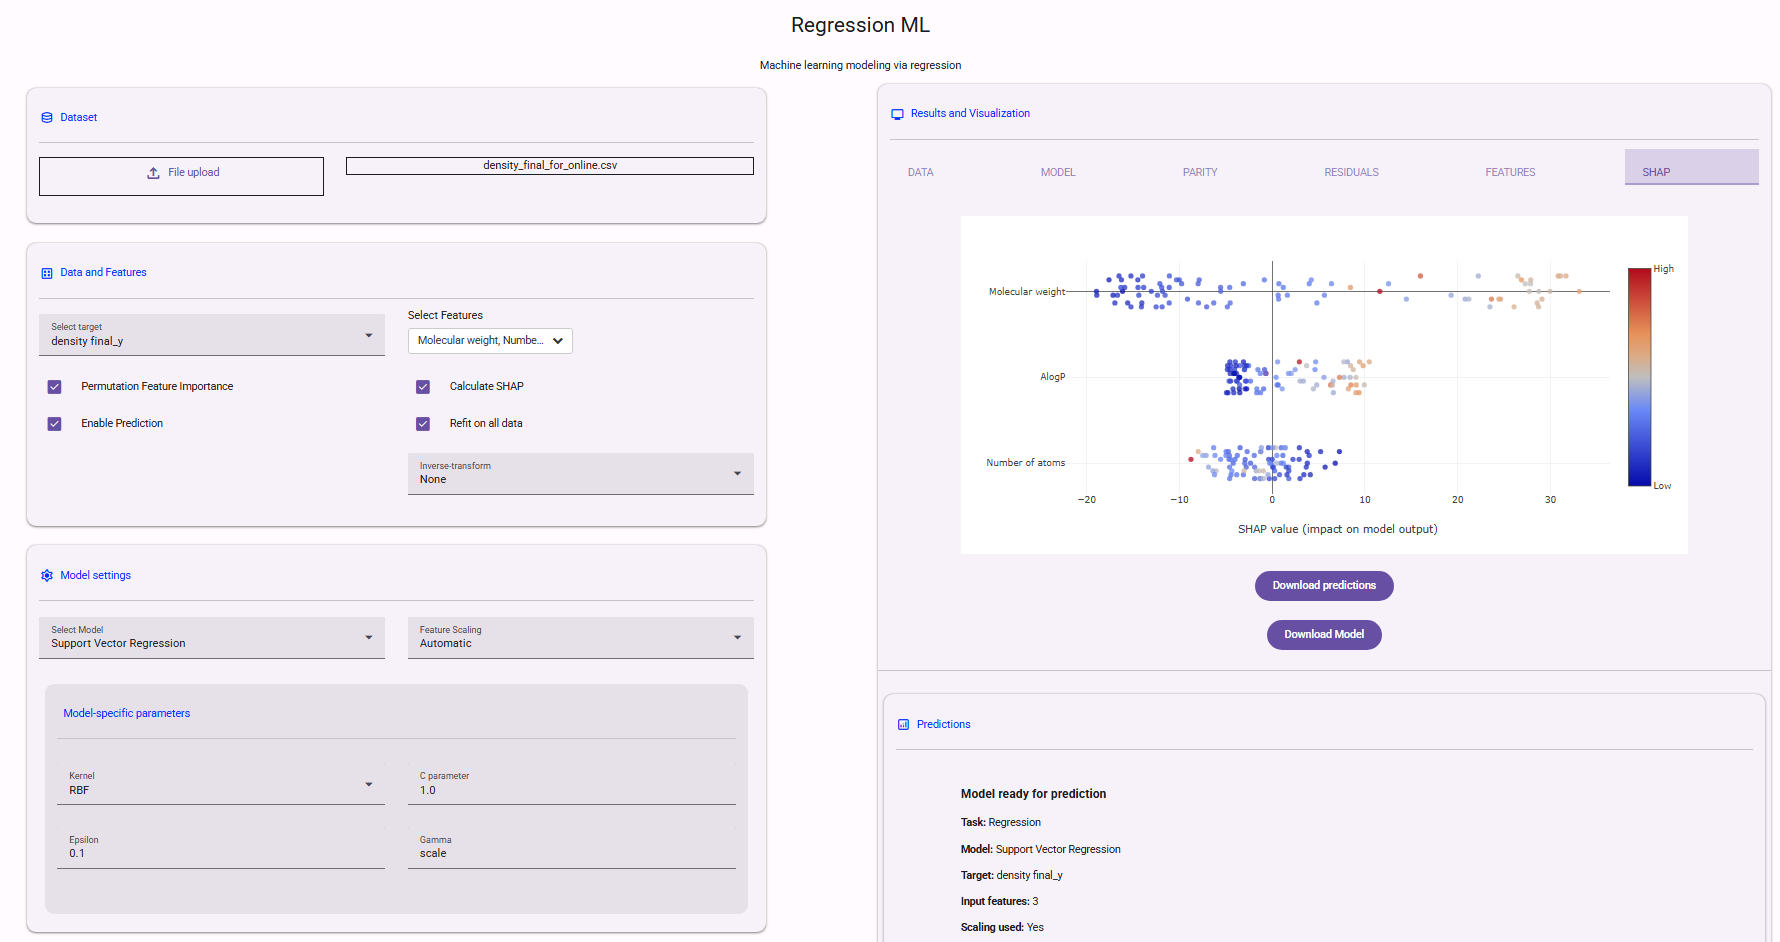
- SHAP Analysis – Interpret model predictions using SHapley Additive exPlanations.
- SHAP Summary Visualizations – Examine the influence of individual features across datasets.
- Feature-Level Interpretation – Identify variables that contribute most strongly to model predictions.
- Classification-Specific SHAP Analysis – Examine feature contributions for individual target classes.
These tools support transparent and scientifically meaningful interpretation of machine learning models, allowing researchers to investigate relationships between input variables and predicted properties.
Model Export and Predictions
Extend machine learning workflows beyond initial model training and evaluation:
- Model Export – Save trained models together with relevant preprocessing information for subsequent use.
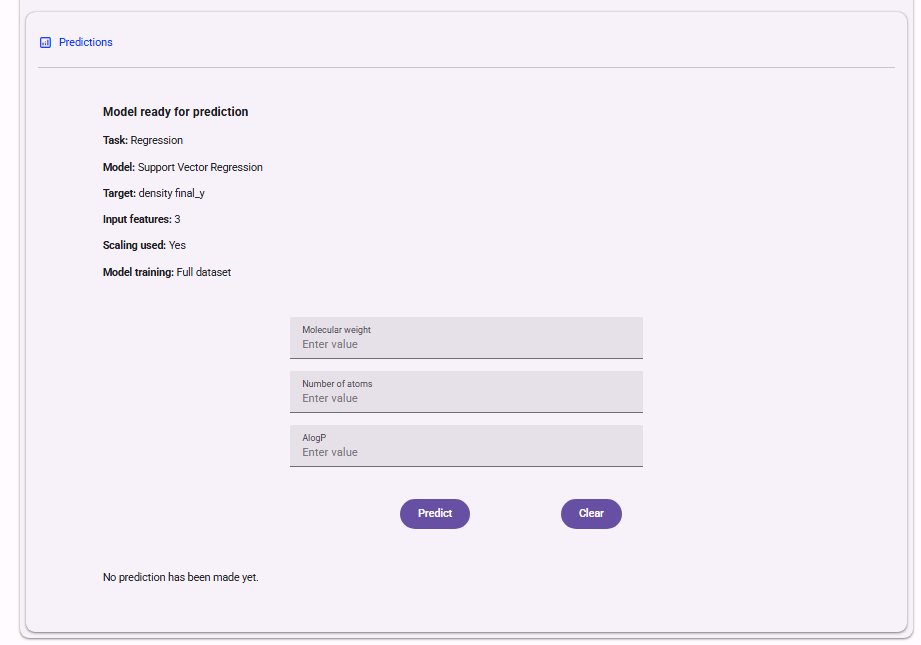
- Prediction on New Data – Apply trained models to new observations using compatible input features.
- Interactive Predictions – Enter feature values directly to generate predictions.
- Inverse Target Transformations – Convert supported transformed regression predictions back to their original physical scale.
- Model Refit – Retrain selected models using the complete available dataset after evaluation.
- Model Reuse – Reuse exported models within supported prediction workflows.
These capabilities are particularly useful for predicting molecular properties, material characteristics, experimental outcomes, and other scientifically relevant quantities.
Why Choose ML Explorer?
- No Programming Required – Develop and evaluate machine learning models through an intuitive graphical interface.
- No Installation Required – Access machine learning tools directly from your web browser.
- Comprehensive Machine Learning Workflows – Combine data preparation, exploratory analysis, model training, validation, interpretation, and prediction within a single platform
- Established Machine Learning Algorithms – Apply widely used regression and classification methods to scientific datasets.
- Advanced Model Interpretation – Explore feature importance and SHAP explanations to better understand model behavior.
- Transparent Performance Evaluation – Examine predictive accuracy through statistical metrics, cross-validation, and graphical diagnostics.
- Designed for Scientific Applications – Suitable for chemistry, physics, materials science, engineering, and other data-driven research fields.
- Research and Education – Support scientific investigations, university teaching, classroom demonstrations, and independent learning.
- Free for Academic Research and Education – Accessible machine learning tools supporting scientific research and educational activities.
- Integrated Scientific Ecosystem – Part of the Atomistica Explorer Suite, alongside tools for atomistic modeling, statistical analysis, and scientific programming.
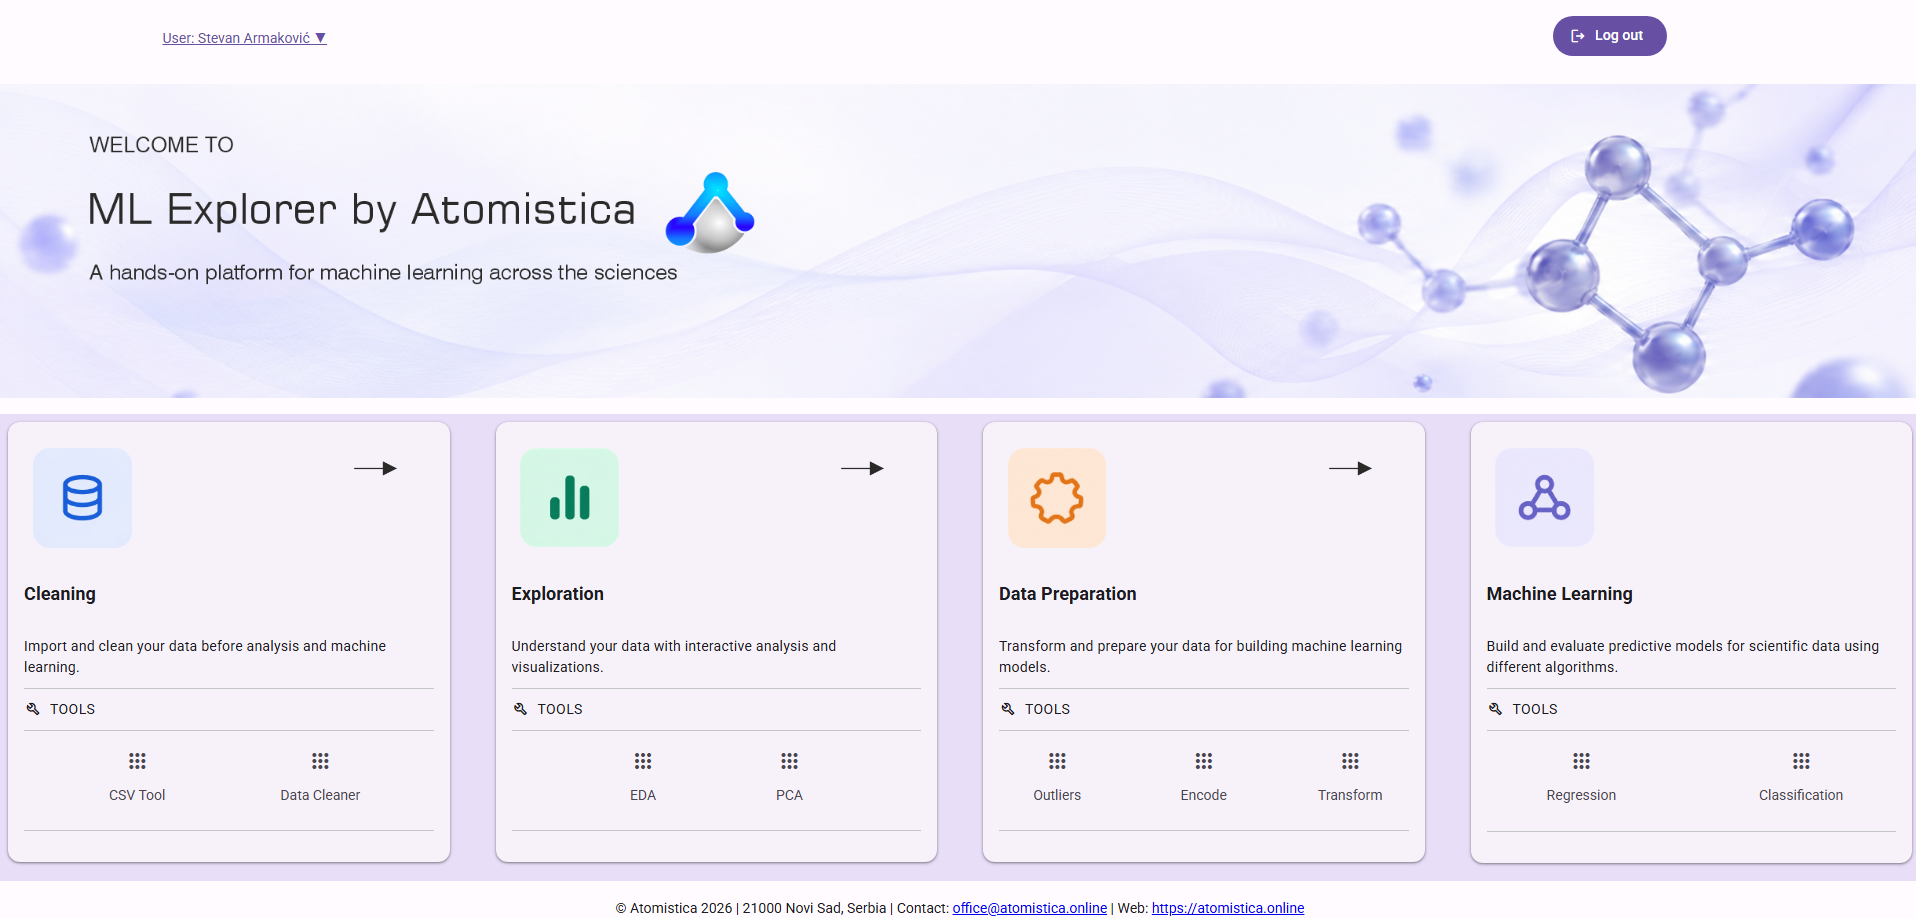
Screenshots from Atomistic Explorer